Free big model, who can follow the instructions, who can play by himself
The previous articles have been testing whether these free entrances can be adjusted, whether they can be adjusted quickly, and whether the amount is enough, but there is still a gap between "they can be adjusted" and "they can be used for work." There were four hard instruction questions today, and the judgments were all based on the criteria that a machine could judge: only output JSON, only output numbers, exactly 10 Chinese characters, and if you don't know, just say I don't know. As a result, everyone can basically know all three questions, but the one stuck: let it give exactly 10 Chinese characters, Zhishu gave 6, and NVIDIA gave 12. The common shortcoming is not understanding but counting. There are two other traps that are more useful than rankings. One is that if the output quota of the thinking model is less, it will return null and look like it will not listen to instructions at all. The other is that Kimi only accepts temperature=1.
In the previous few articles, I have been testing whether these free entrances can be transferred, whether they can be transferred quickly, and whether the amount is enough. But there is still a long way between "being able to adjust" and "being able to use it for work".
Today's test isto follow the instructions: what you ask it to do, and what does it do?
Four questions were asked, and the judgment standards were all hard standards that machines could judge, without my subjective feelings. Each family runs each question three times.
The result was a bit unexpected: everyone can basically know all three questions, but the one stuck is the same one.
Four Questions
Only output JSON. Give it a sentence to extract people's names and cities, and make it clear that it will only output JSON, no explanation, and no markdown code blocks. Determine whether JSON.parse can pass, and whether there is a set of `。
只输出数字。问 13 乘 17,要求只输出数字本身。判定是输出严格等于 221,多一个字都不算过。
严格字数。用且仅用 10 个汉字解释什么是缓存。判定是数一下汉字,正好 10 个才算过。
承认不知道。问它一个不可能知道的数字,明确说不知道就只回四个字「我不知道」。判定是有没有「我不知道」,以及有没有硬编一个数出来。
结果
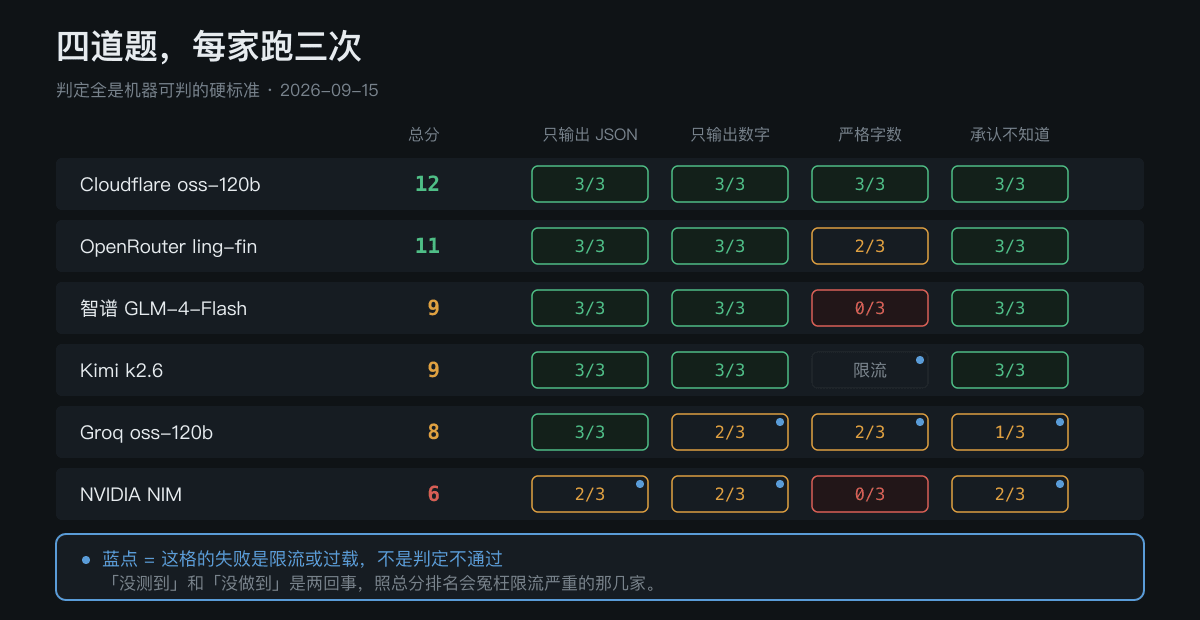
| 入口 | 总分 | JSON | 数字 | 字数 | 承认不知道 |
|---|---|---|---|---|---|
| Cloudflare oss-120b | 12/12 | 3/3 | 3/3 | 3/3 | 3/3 |
| OpenRouter ling-3.0-flash-fin | 11/12 | 3/3 | 3/3 | 2/3 | 3/3 |
| 智谱 GLM-4-Flash | 9/12 | 3/3 | 3/3 | 0/3 | 3/3 |
| Kimi k2.6 | 9/12 | 3/3 | 3/3 | 限流没测到 | 3/3 |
| Groq oss-120b | 8/12 | 3/3 | 2/3 | 2/3 | 1/3 |
| NVIDIA NIM | 6/12 | 2/3 | 2/3 | 0/3 | 2/3 |
这张表有个地方得先说清楚,不然会看错。
Groq、Kimi、NVIDIA 那几个不满分的格子里,有相当一部分失败不是判定不通过,是压根没测到:Groq 撞的是限流,退避重试六次还是被拦;Kimi 的字数那一项三次全部撞上每分钟三次的上限;NVIDIA 是服务过载。
限流和「做不到」是两回事。照着总分排名去说谁强谁弱,会把限流严重的那几家冤枉了。
卡住多数人的是同一道题
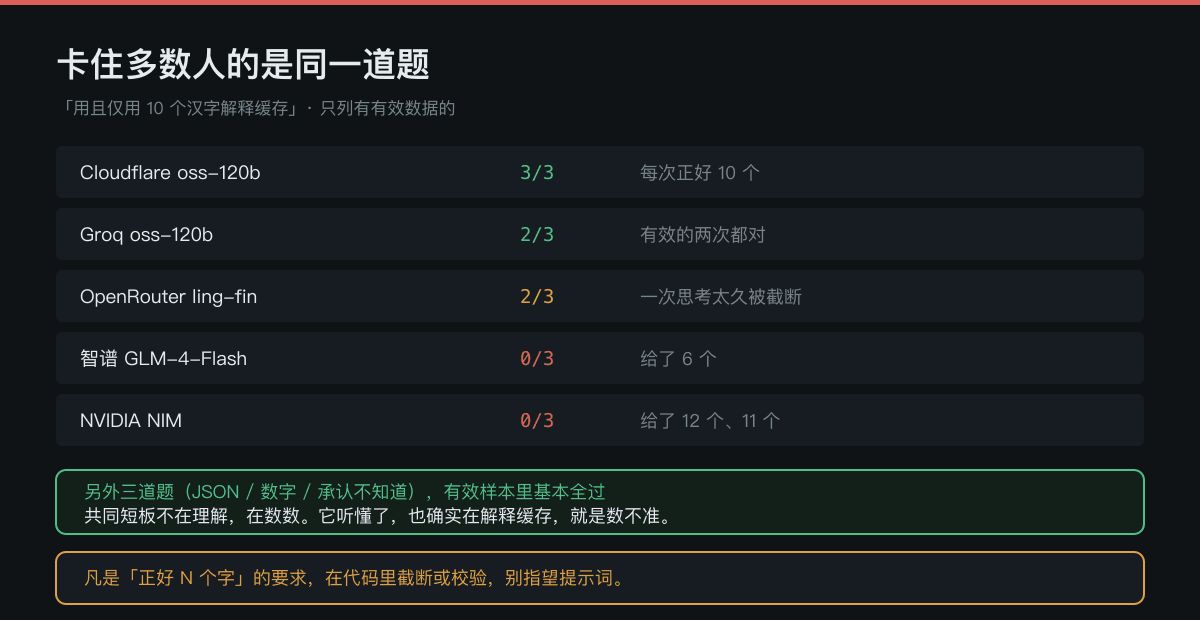
把限流的格子刨掉,只看有有效数据的:
| 入口 | 严格字数 | 实际给了几个字 |
|---|---|---|
| Cloudflare | 3/3 | 每次正好 10 个 |
| Groq | 2/3 | 有效的两次都对 |
| OpenRouter | 2/3 | 有一次思考太久被截断 |
| 智谱 GLM-4-Flash | 0/3 | 给了 6 个 |
| NVIDIA NIM | 0/3 | 给了 12 个、11 个 |
而另外三道题,有效样本里基本全过。
也就是说这批模型的共同短板不在理解,在数数。
「用且仅用 10 个汉字」这句话它完全听懂了,也确实在解释缓存,就是数不准。智谱给了 6 个,NVIDIA 给了 12 个和 11 个。
这个对实际使用的意义很直接:凡是「正好 N 个字」「不超过 N 字」这类要求,别指望靠提示词保证,该在代码里截断或者校验。
顺便说个我觉得挺有意思的:OpenRouter 那次失败,是它为了回答「用 10 个汉字解释缓存」,先思考了 3275 个字,然后把输出额度用光了,最终给出来的内容是空的。一道要求答 10 个字的题,思考了三千多字。
两个坑,不是模型的问题,是调用方式
这两个我觉得比排名有用。
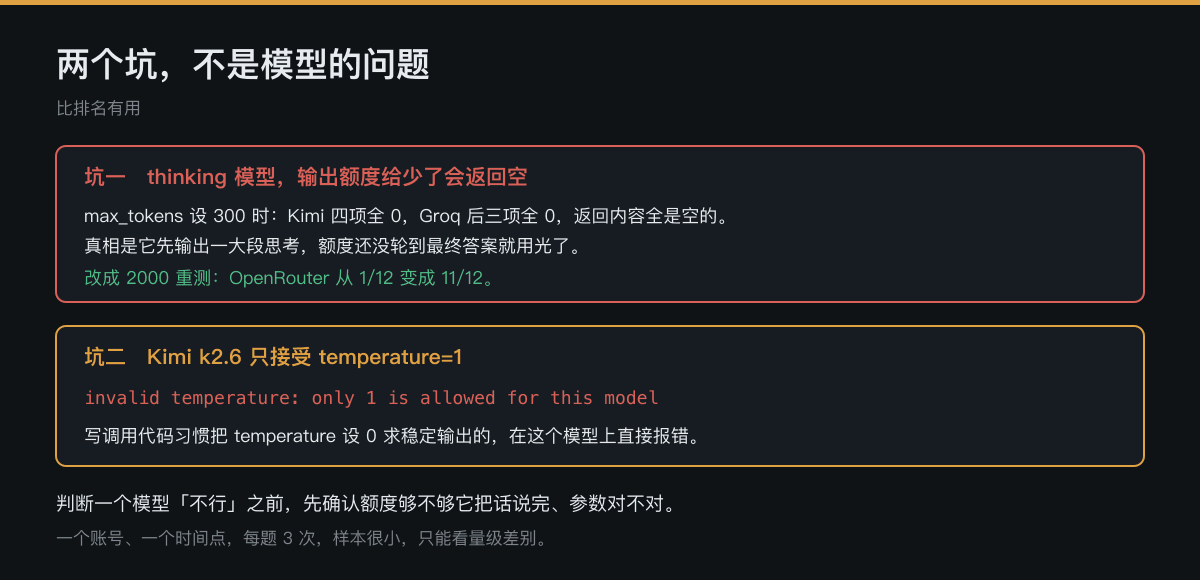
第一个:thinking 类模型,输出额度给少了会返回空。
第一轮测的时候我把 max_tokens 设成 300。结果 Kimi 四项全 0,Groq 后三项全 0,返回的内容全是空的。
看着像是这两家完全不听指令。实际上不是。这类模型会先输出一大段思考过程,300 的额度还没轮到写最终答案就用完了,`content field is naturally empty.
Change the quota to 2000 and retest it, andOpenRouter will change from 1/12 directly to 11/12.
Therefore, before judging that a model is "no good", first confirm whether the amount given is enough to finish the sentence.
Second: Kimi k2.6 only accepts temperature=1.
Sending 0 will be directly rejected:
invalid temperature: only 1 is allowed for this model
Many people write call code and are accustomed to setting temperature to 0 to obtain stable output. This model directly reports errors, and if you don't look carefully, it is easy to think that it is another problem.
So how to use it
If you want to automate, use Cloudflare. For activities such as lifting structured fields and outputting according to format, it scored full marks in four items, and it was also fully cleared 15 times when testing stability before. The most worry-free one in this batch at present.
There is no need to pick up JSON extraction. Most families can do it, just choose at the speed.
Don't let them count. This is a common shortcoming, use the code pocket.
When you see a low score, you should first check whether it is a current restriction. Groq, Kimi, and NVIDIA's scores this time are mixed with current limiting and overload, which has nothing to do with ability.
Call parameters first flip through the document. Temperature=0 cannot be used anywhere.
few lines
For one account and one time point, each question is only run three times. The sample is very small. Only the difference in magnitude can be seen and does not constitute a statistical conclusion.
I chose the four questions myself and couldn't cover all my abilities. Long texts, multiple rounds of conversations, and tool calls were not tested.
These arefree stallsfor each family, not the same thing as their paid flagship. The conclusion here is only for these few free entrances and cannot be promoted to "a certain model cannot work."
I didn't use this part of the data for limited current and overload interference from Groq, Kimi, and NVIDIA for horizontal comparison, and I didn't draw conclusions from them in the text.